 NEW
Qlik to dbt migration
AI
Proof
Pricing
Book a demo
Get the free assessment
NEW
Qlik to dbt migration
AI
Proof
Pricing
Book a demo
Get the free assessment
Targets
Warehouses
Runtimes
Before migration
After migration
DATA step, PROC SQL, and macros parsed structurally. Emitted as set-based PySpark you can run on Databricks, EMR, or your own cluster.
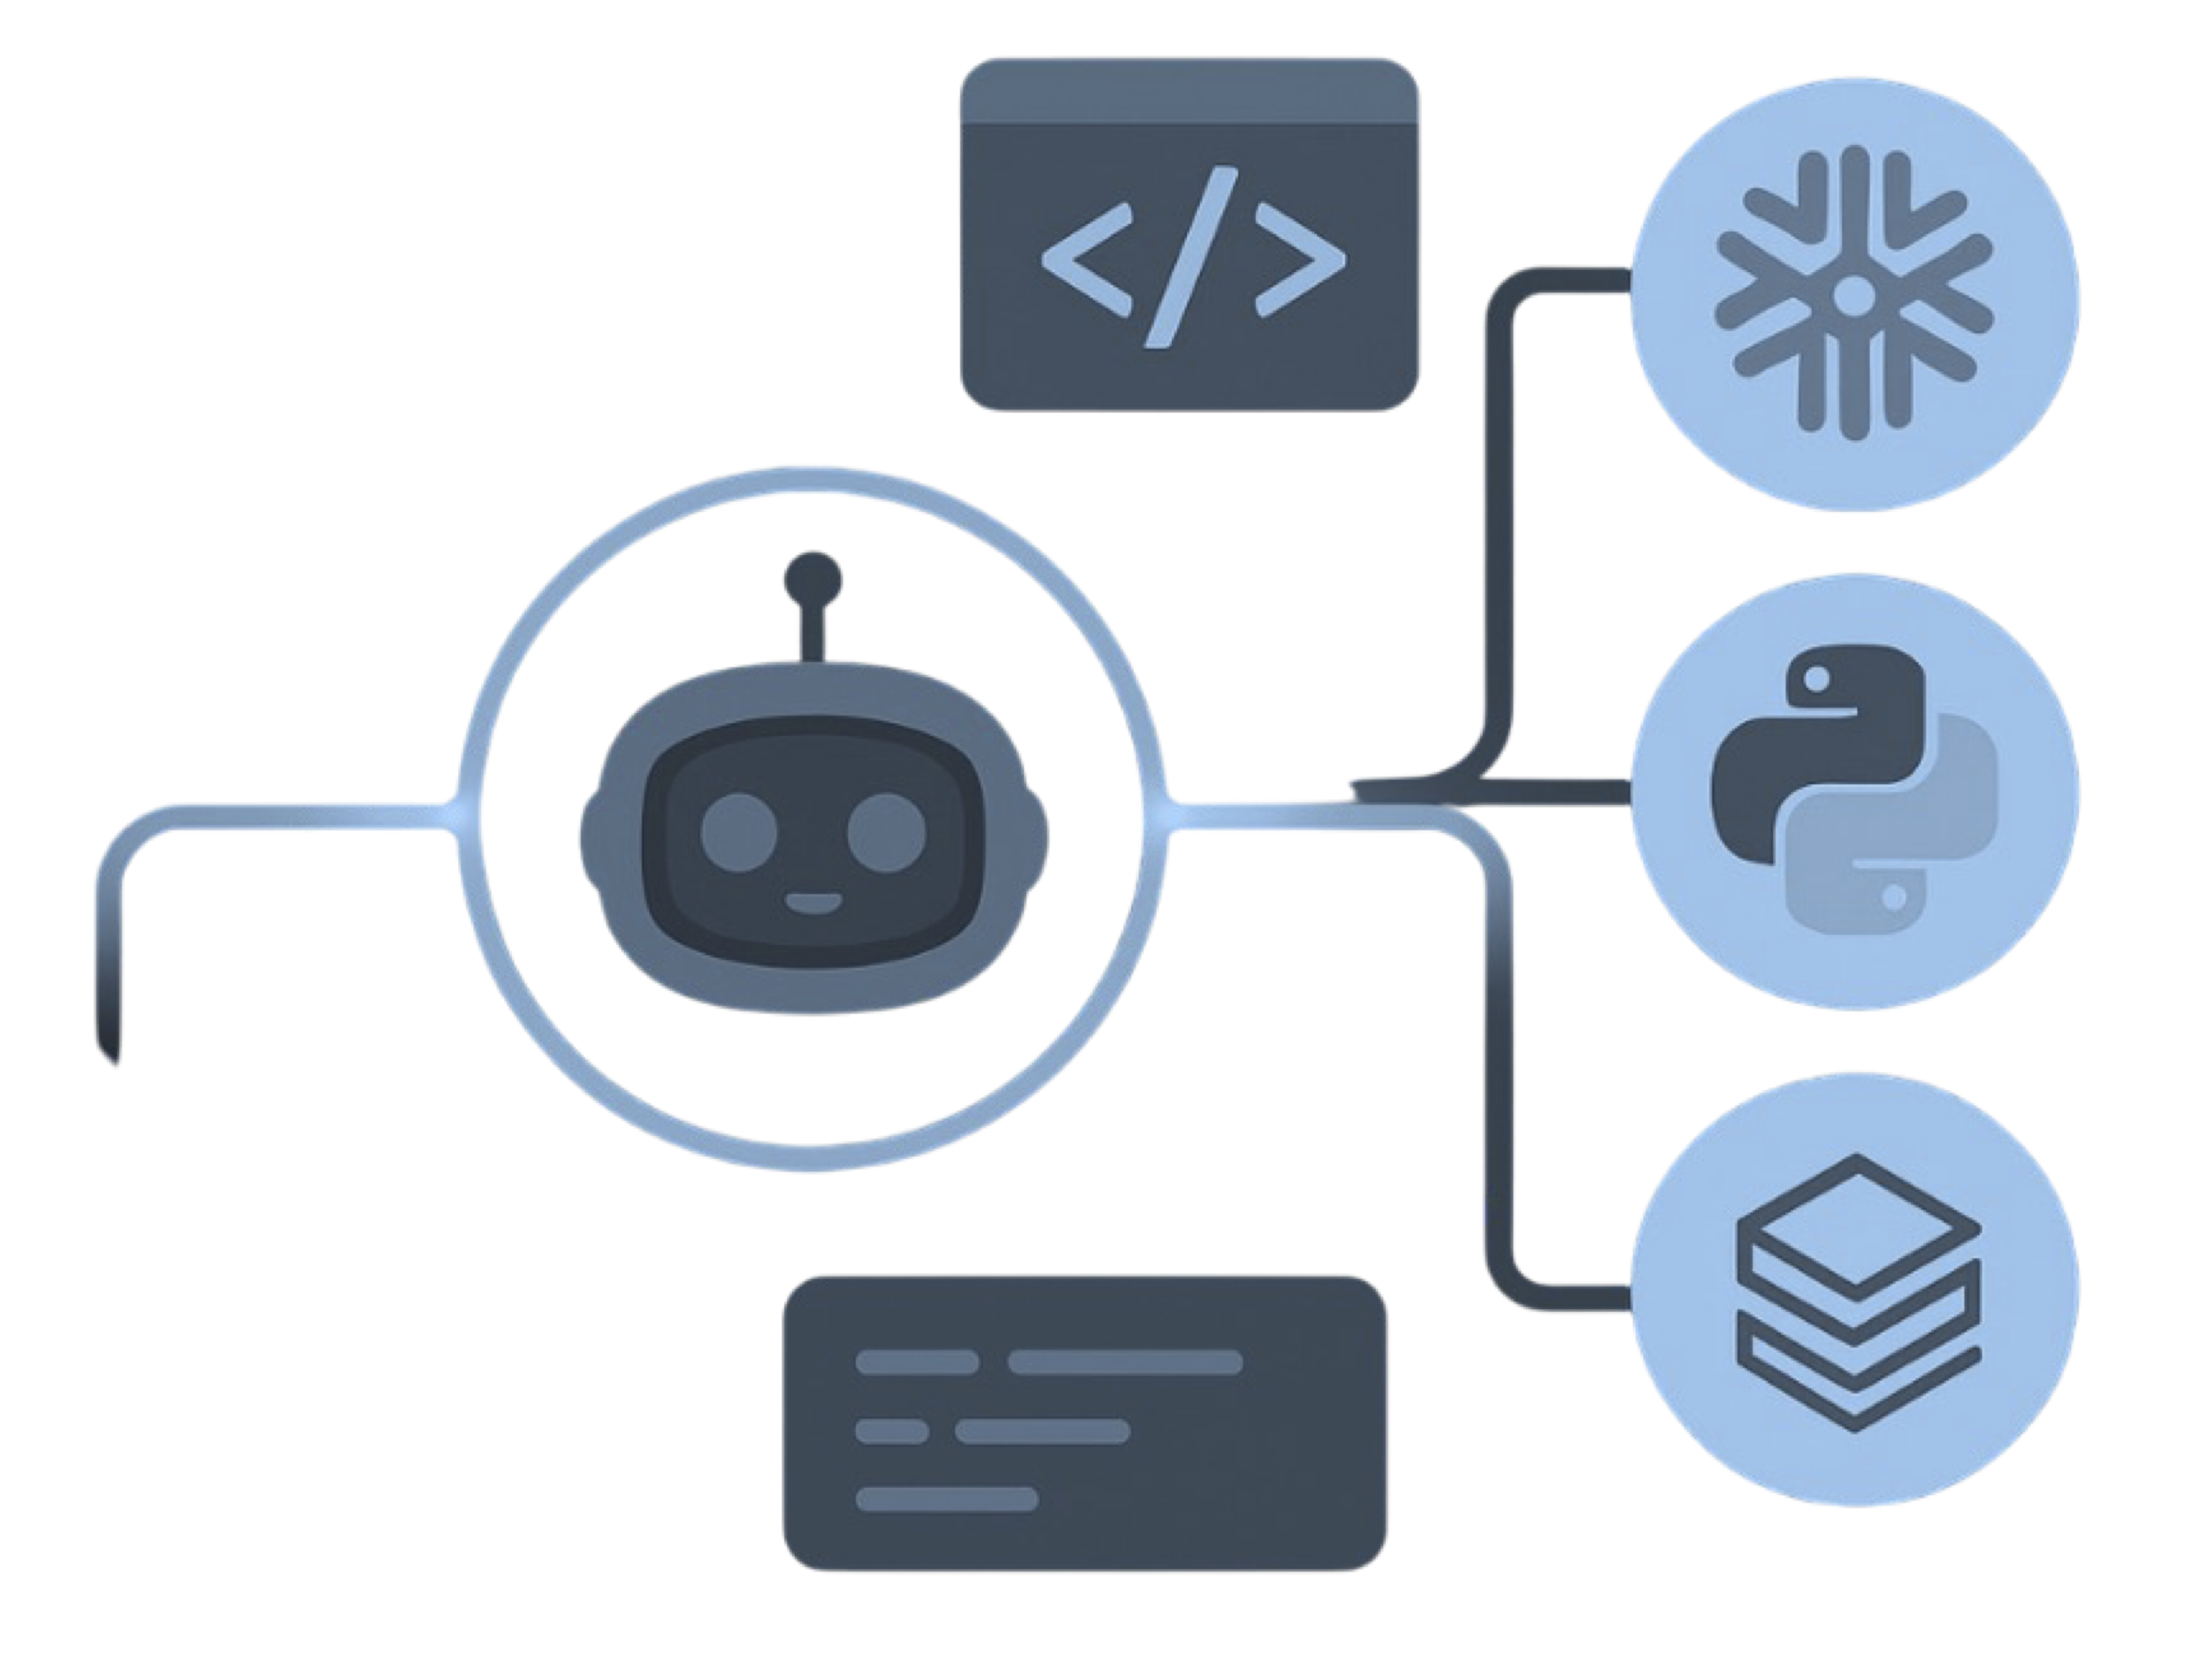
Deterministic parsers read the SAS estate and emit native PySpark code, not a Python while-loop that still reads one row.
SAS programs → SAS2PY parser → Native PySpark
 SAS
Base SAS
DATA step / macros
DI Studio
Jobs + mappings
EG / EM
Projects + flows
Viya / CAS
CASL + actions
 SAS2PY Parser
 Deterministic parse
AI where it helps
 Row-level parity
Before cutover
 PySpark emit
Set-based
Notebook / .py
Your repo
PySpark
PySpark
DataFrames
 Python modules
Reusable
Git
Reviewed diffs
 Any cluster
Databricks / EMR / k8s
MigryX AI handles the logic parsers cannot resolve alone, and every change it makes goes through the same parity checks. It runs on a model you approve, air-gapped if your estate requires it.
A for-loop over a SAS dataset is the same program in a new costume. We emit joins, windows, and aggregations.
Databricks, EMR, or on-prem Spark: the parser does not care. The notebook is portable.
Expanded before emit. The output is Python a Spark engineer can read.
A row-at-a-time running total, emitted as a filter and window, not a Python for-loop.
/* SAS row loop */
data gold;
  set txn;
  if amount > 1000;
  tot + amount;
run;
# loop → filter + window
from pyspark.sql import functions as F
from pyspark.sql.window import Window
gold = txn.filter(F.col("amount") > 1000).withColumn(
    "tot", F.sum("amount").over(Window.orderBy("txn_date"))
)
The running total is a window. The filter is a predicate. No iterator.
| SAS | PySpark | Notes |
|---|---|---|
| DATA step | DataFrame API | No row loops |
| PROC SQL | spark.sql | Same joins |
| PROC MEANS / SUMMARY | groupBy + agg | Native |
| Macro | Expanded Python | Readable |
| SAS dataset | Parquet / Delta / Iceberg | Your choice |
SAS output compared to PySpark output: row by row, column by column. Differences flagged before sign-off.
See how Data Matching works →Nine SAS-to-PySpark engagements in all, across banks in North America, the UK, Asia, and Oceania. Customer names are shared under NDA in a demo, with reference calls on request.
See all engagements →