
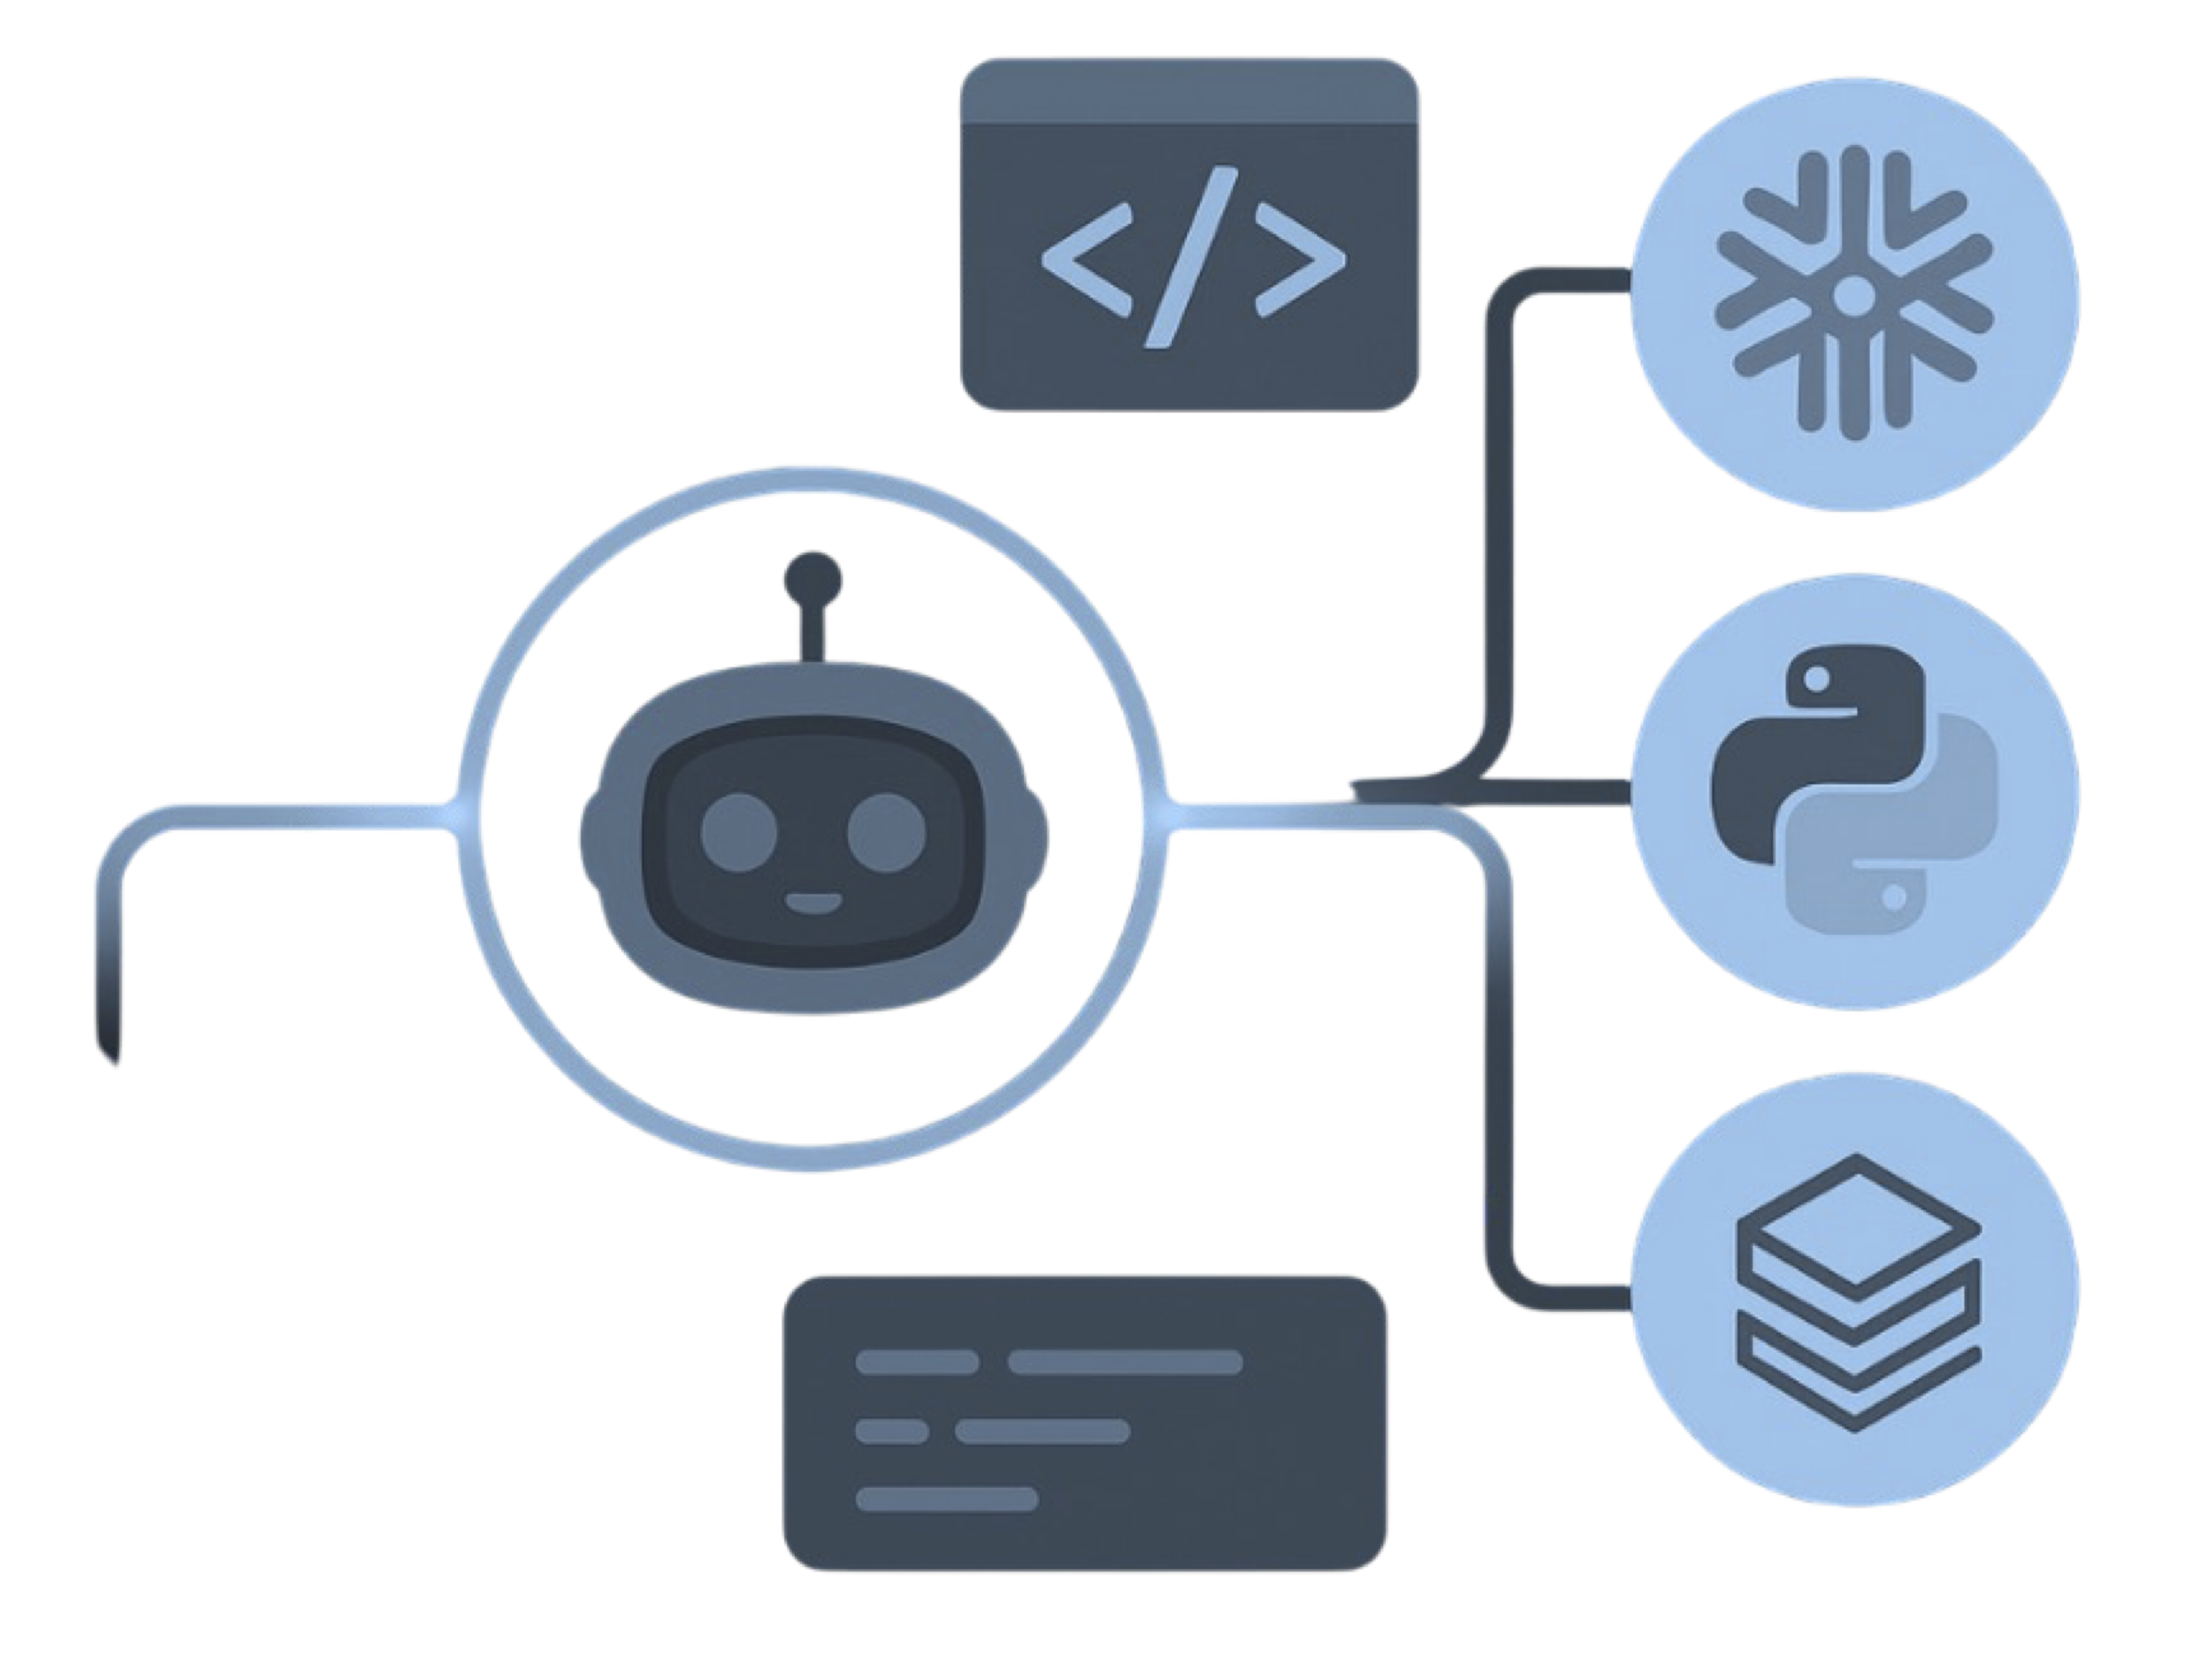
 Deterministic parse
AI where it helps
 Expression emit
DATA step → LazyFrame
 SQL routing
Polars or DuckDB
 Lake ingest
Iceberg → Polars
 Kubernetes
When you need a fleet
Migrating SAS to Polars with MigryX: LazyFrame Pipelines at Scale
SAS has been the backbone of enterprise analytics for decades, powering regulatory reporting, risk modeling, clinical trials, and data preparation across banking, insurance, healthcare, and government. But the economics and technical landscape have shifted. SAS licensing costs continue to climb, the talent pool is shrinking, and modern alternatives deliver superior performance at a fraction of the cost. The question is no longer whether to migrate, it is where to migrate to.
For organizations that need speed, simplicity, and Python-native tooling without the overhead of a Spark cluster, Polars is emerging as a compelling target. This article explains how MigryX converts SAS programs to idiomatic Polars LazyFrame pipelines, with practical examples and performance comparisons.
Why SAS to Polars?
Three forces are driving SAS-to-Polars migration decisions simultaneously.
Licensing costs. SAS licensing is notoriously expensive: annual costs for enterprise deployments routinely reach seven figures. Polars is MIT-licensed and free. The savings are not marginal; they are transformational, often funding the entire migration project and still leaving budget to spare.
The Python ecosystem. Python has become the lingua franca of data engineering, data science, and machine learning. Moving from SAS to Python means access to thousands of libraries, a massive talent pool, seamless integration with cloud platforms, and the ability to embed analytics into applications rather than running them in isolated SAS environments.
Polars' performance advantage. The traditional migration path from SAS has been to pandas, but pandas struggles with the dataset sizes that SAS handles routinely. A SAS program processing 50 million rows runs comfortably; the same logic in pandas can exhaust memory or take hours. Polars closes this gap. Its multi-threaded Rust engine and lazy evaluation deliver performance that meets or exceeds SAS for data preparation workloads, typically at 5-20x the speed for equivalent operations.
SAS to Polars Mapping
SAS constructs do not map one-to-one to Polars. Each requires careful decomposition, and the complexity varies significantly depending on the patterns involved.
| SAS Construct | Complexity | Key Challenge |
|---|---|---|
| DATA step | High | Implicit output, variable retention, and conditional logic require decomposition into LazyFrame chains |
| PROC SQL | Medium | SAS SQL extensions (calculated, monotonic, INTO) have no direct Polars equivalents |
| SAS Macros | High | Text substitution semantics, nested macro calls, and conditional compilation require full expansion before translation |
| MERGE with BY | Medium-High | SAS merge behavior differs from standard joins: especially with duplicate keys and IN= dataset options |
| RETAIN / BY-group state | High | Row-level state tracking across groups requires mapping to window expressions and cumulative functions |
MigryX handles the full SAS construct landscape, generating idiomatic Polars code that leverages lazy evaluation and expression-based APIs.
Code Comparison: SAS DATA Step vs. Polars LazyFrame
Consider a typical SAS DATA step that merges two datasets, applies a filter, and computes a derived column. This pattern appears in virtually every SAS codebase.
SAS
data work.combined;
    merge work.orders(in=a) work.customers(in=b);
    by customer_id;
    if a and b;
    if order_amount > 100;
    profit = order_amount - cost;
    margin = profit / order_amount;
    length tier $10;
    if margin >= 0.3 then tier = 'HIGH';
    else if margin >= 0.15 then tier = 'MEDIUM';
    else tier = 'LOW';
run;
MigryX converts this multi-step DATA step (with its merge, filter, derived columns, and conditional logic) into an optimized Polars LazyFrame pipeline that leverages expressions and lazy evaluation for maximum performance. The Polars optimizer pushes filters down to the data source, skips reading unused columns, and executes joins and computations in parallel across all CPU cores. The SAS version processes rows sequentially in a single thread.
Handling SAS-Specific Patterns
SAS has idioms that do not map directly to standard DataFrame operations. MigryX handles these patterns with purpose-built translation logic.
RETAIN and Running State
SAS RETAIN statements (used for running totals, lag values, and group boundary detection) are among the trickiest patterns to translate. Polars' expression API handles these elegantly, but the translation requires deep understanding of both paradigms. MigryX handles all RETAIN patterns automatically.
BY-Group Processing
SAS DATA steps with BY statements process data group-by-group, with automatic FIRST. and LAST. variables. Polars handles this through .group_by() with aggregation expressions, or through .over() window expressions when row-level output is needed. MigryX detects BY-group patterns in the DATA step logic and selects the appropriate Polars construct.
ARRAY Processing
SAS arrays iterate over a set of columns within a DATA step: typically for scoring, recoding, or applying the same transformation to multiple variables:
array scores{5} score1-score5;
do i = 1 to 5;
    scores{i} = scores{i} * 1.1;
end;
SAS ARRAY processing requires decomposition into Polars horizontal operations: a non-trivial restructuring that MigryX handles automatically.
FORMAT and INFORMAT
SAS formats and informats control how values are displayed and read: a concept with no direct parallel in Python DataFrames. Date formats, numeric widths, and character informats all require careful translation to appropriate data types. MigryX automatically maps SAS formats and informats to appropriate Polars data types.