
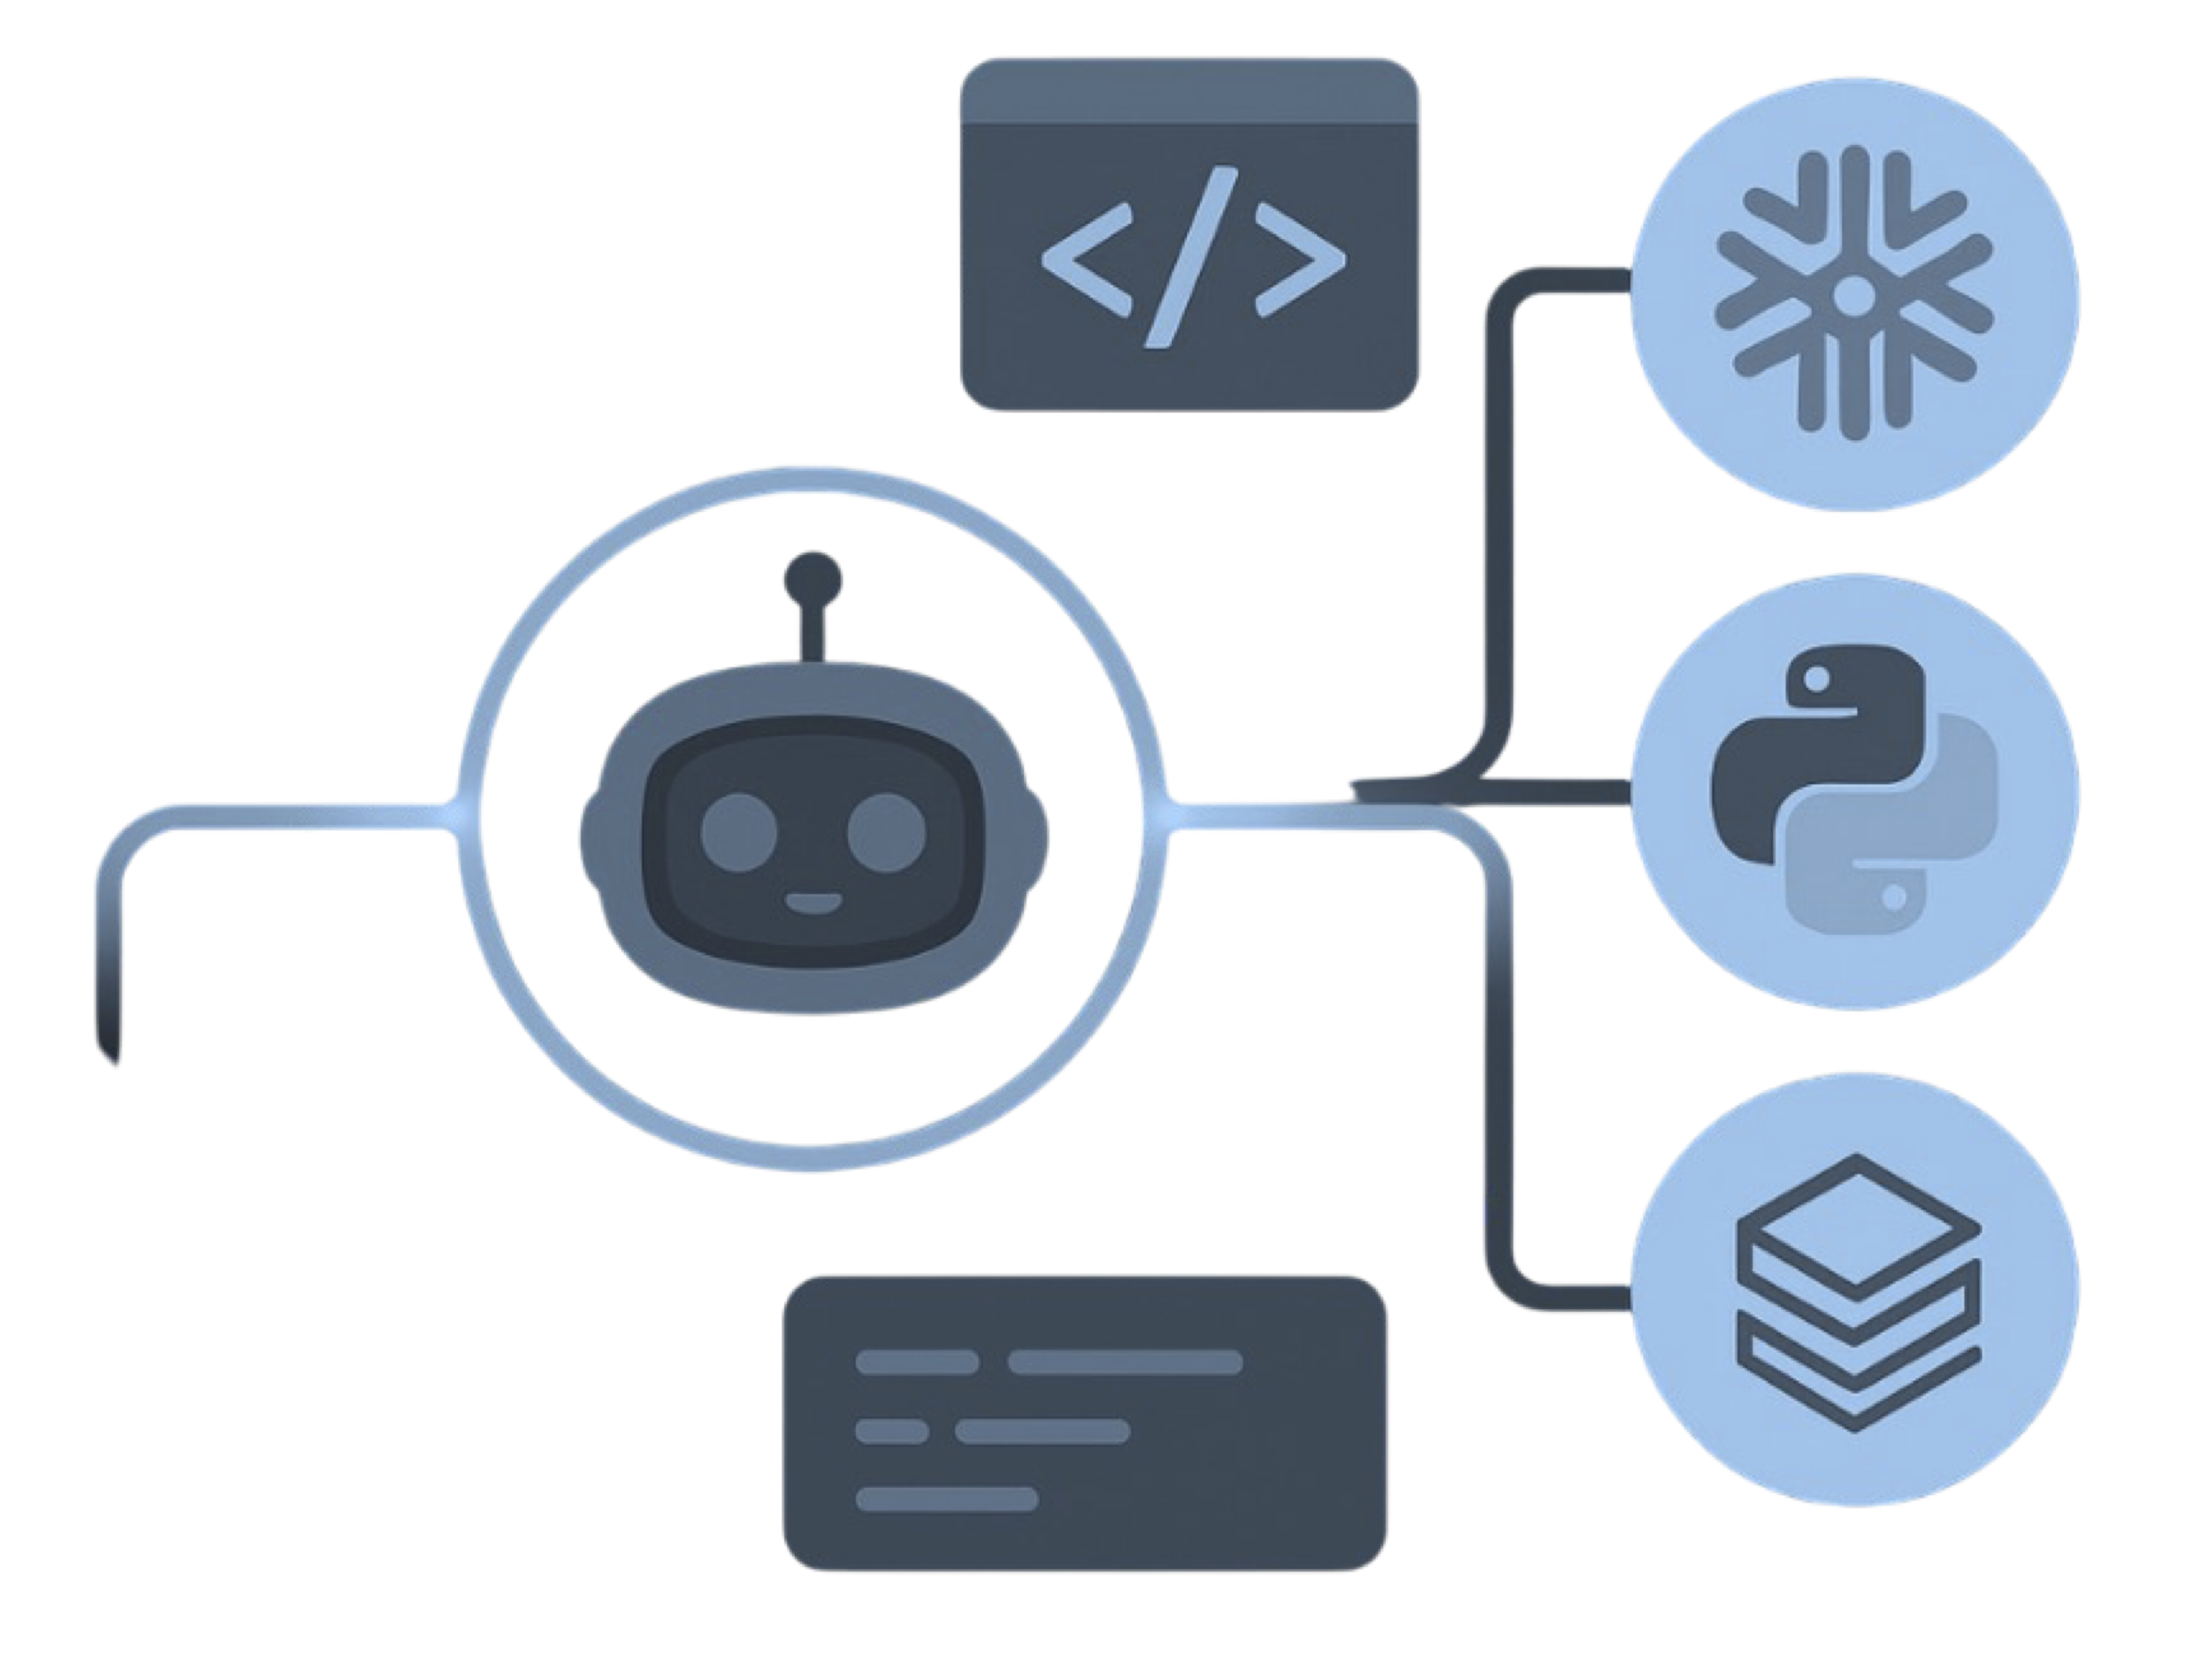
 Deterministic parse
AI where it helps
 Row-level parity
Before cutover
 Spark emit
Notebooks
 Pipeline emit
ADF / Fabric
 Unity Catalog
When on Databricks
 Python jobs
Non-SQL remainder
Migrating SAS Workloads to Azure Fabric with MigryX
SAS has been the backbone of enterprise analytics for decades. Banks run credit risk models in SAS. Insurers calculate reserves in SAS. Government agencies produce official statistics in SAS. But the economics and architecture of analytics are shifting, and Microsoft Fabric is emerging as the destination platform for organizations ready to leave legacy licensing behind.
This guide walks through the practical reality of migrating SAS workloads to Azure Fabric, from construct-level mapping to validation strategies, with a focus on how MigryX automates the heavy lifting.
Why SAS Teams Are Choosing Fabric
Three forces are converging to push SAS shops toward Fabric: licensing costs, skill availability, and the shift to cloud-native architectures.
Licensing costs are the most visible pressure. SAS licenses are typically structured as annual subscriptions tied to server capacity or named users. For large enterprises, this runs into seven figures annually, and the cost scales with usage in ways that discourage experimentation and broad adoption. Fabric's capacity-based pricing model means teams pay for compute when they use it, and Power BI's included visualization eliminates separate BI licensing entirely.
Skill availability is the quieter but equally urgent problem. The pool of experienced SAS programmers is shrinking as universities shift curricula toward Python and SQL. Meanwhile, the Fabric ecosystem (PySpark, T-SQL, Python notebooks) draws from the largest talent pools in data engineering. Organizations that stay on SAS increasingly find themselves competing for a dwindling number of specialists at premium rates.
Cloud-native architecture is the structural shift. SAS was designed for a world of on-premise servers and batch processing. Fabric is designed for elastic cloud compute, real-time streaming, and integrated machine learning. Features like automatic scaling, built-in Copilot AI assistance, and native integration with Azure DevOps represent capabilities that cannot be retrofitted onto a forty-year-old architecture.
SAS-to-Fabric Construct Mapping
The first question every SAS team asks is: "What does my SAS code become in Fabric?" The answer depends on the specific construct. Here is the mapping that MigryX applies:
| SAS Construct | Fabric Target | Notes |
|---|---|---|
| SAS DATA step | Fabric Spark Notebooks | Row-level logic becomes PySpark DataFrame operations |
| PROC SQL | Data Warehouse T-SQL | SQL translation with Fabric dialect adjustments |
| SAS Macros | Python functions / Jinja templates | Parameterization and nesting preserved |
| LIBNAME statements | OneLake lakehouse connections | Library references become lakehouse paths |
| SAS Scheduler | Data Factory pipelines | Scheduling, dependencies, and alerting included |
Step-by-Step Migration Workflow
MigryX structures the SAS-to-Fabric migration into five distinct phases, each with clear inputs and outputs:
- Ingest SAS programs. MigryX scans the SAS estate (programs, macros, autoexec files, format catalogs, and scheduling metadata) and builds a complete inventory. Dependency graphs are generated automatically, showing which programs depend on which macros, which datasets feed which downstream consumers, and where circular dependencies exist.
- Deep code analysis. MigryX deeply analyzes your SAS code, understanding every construct, dependency, and behavioral nuance before generating Fabric-native code.
- Automated conversion to Fabric artifacts. MigryX produces the appropriate Fabric artifact for each construct. DATA steps become PySpark notebooks. PROC SQL becomes Data Warehouse T-SQL. Scheduling logic becomes Data Factory pipelines. Each generated artifact includes error handling, logging, and parameterization aligned with Fabric best practices.
- Validation against SAS output. MigryX generates validation queries that compare SAS output datasets against Fabric output tables, row counts, column schemas, aggregate statistics, and cell-level comparisons. Validation runs automatically as part of the migration pipeline, producing pass/fail reports for every converted program.
- Deploy to Fabric workspace. Validated artifacts are deployed to the target Fabric workspace using Fabric's REST APIs and Git integration. Notebooks, warehouse objects, and Data Factory pipelines are version-controlled and deployed through the organization's standard CI/CD process.
Code Examples: Before and After
Example 1: SAS PROC SQL with Macro Variables to Fabric Data Warehouse SQL
SAS Source:
%let cutoff_date = '2024-01-01';
%let min_balance = 10000;

PROC SQL;
  CREATE TABLE work.high_value_customers AS
  SELECT
    c.customer_id,
    c.customer_name,
    a.account_type,
    SUM(t.amount) AS total_transactions,
    MAX(t.transaction_date) AS last_activity
  FROM customers c
  INNER JOIN accounts a
    ON c.customer_id = a.customer_id
  INNER JOIN transactions t
    ON a.account_id = t.account_id
  WHERE t.transaction_date >= &cutoff_date
    AND a.balance >= &min_balance
  GROUP BY c.customer_id, c.customer_name, a.account_type
  HAVING SUM(t.amount) > 50000
  ORDER BY total_transactions DESC;
QUIT;
What MigryX generates: MigryX generates equivalent Fabric T-SQL with proper variable declarations, type mappings, and null handling.
Example 2: SAS DATA Step Merge to PySpark in Fabric Spark Notebook
SAS Source:
PROC SORT DATA=orders; BY customer_id; RUN;
PROC SORT DATA=returns; BY customer_id; RUN;

DATA order_summary;
  MERGE orders (IN=a) returns (IN=b);
  BY customer_id;
  IF a;
  IF b THEN return_flag = 1;
  ELSE return_flag = 0;
  net_amount = order_amount - COALESCE(return_amount, 0);
RUN;
What MigryX generates: MigryX converts MERGE operations to optimized PySpark joins, correctly interpreting IN= variables and BY-group semantics.
Validation Strategy
Conversion without validation is guesswork. MigryX builds validation into the migration pipeline as a first-class concern, not an afterthought. The validation strategy operates at four levels:
- Row-level comparison. For every converted program, MigryX compares the SAS output dataset against the Fabric output table row by row. Numeric columns are compared within a configurable tolerance (typically 0.01 for financial data) to account for floating-point differences between SAS and Spark. String columns are compared after normalization for trailing spaces and case.
- Aggregate validation. Sums, counts, distinct value counts, min/max values, and mean calculations are compared across all numeric columns. This catches systematic errors, like an incorrect join type producing duplicate rows, that row-level sampling might miss.
- Schema validation. Column names, data types, nullability constraints, and column order are validated against the expected schema. SAS's implicit type coercions (character-to-numeric and vice versa) are explicitly flagged and verified.
- Automated validation queries. MigryX generates the validation queries themselves: SQL scripts that run against both SAS output (exported to OneLake) and Fabric output tables. Results are compiled into a validation report with pass/fail status for every program, every table, and every column.
OneLake Lineage Registration
Migration is not complete when the code runs correctly. Governance requires that every data asset in the target environment is documented, traceable, and auditable. This is where OneLake lineage registration becomes critical.
After conversion, MigryX publishes column-level lineage to the OneLake catalog. This lineage maps every source SAS column through every transformation step to the target Fabric table column. The result is a complete graph showing:
- Source-to-target mapping. Which SAS dataset and column produced each Fabric table column.
- Transformation logic. What calculations, filters, joins, and aggregations were applied at each step.
- Cross-artifact dependencies. How Spark notebooks feed Data Warehouse tables, which feed Power BI datasets.
- Impact analysis. If a source column changes, which downstream Fabric tables and reports are affected.
This lineage is registered using Fabric's native catalog APIs, meaning it is visible in the Fabric portal alongside all other metadata. Governance teams do not need a separate lineage tool. They can trace data flows directly in the platform they already use.
For regulated industries, this capability is not optional. Financial regulators expect institutions to demonstrate full traceability from source data to reported metrics. Healthcare organizations need HIPAA-compliant data flow documentation. Government agencies require audit trails for every data transformation. MigryX's automatic lineage registration satisfies these requirements from day one of the migration, rather than as a separate post-migration project.
Migrating SAS to Azure Fabric is a significant undertaking, but it is a tractable one when approached with the right tools and methodology. The construct mappings are well-defined, the conversion workflow is repeatable, the validation strategy is automated, and the governance requirements are addressed natively. MigryX transforms what would be a multi-year manual effort into a structured, measurable, and auditable migration program.